About Chroma
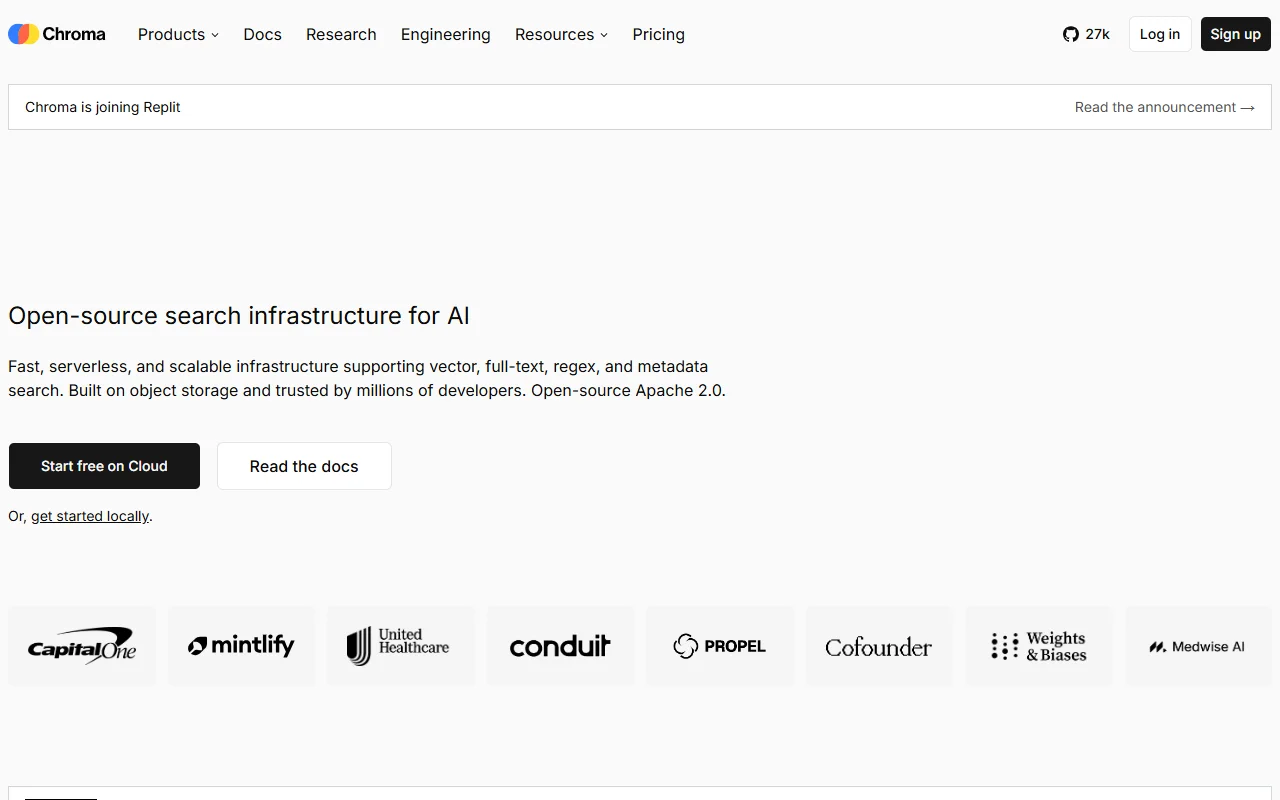
Chroma is an open source search database for AI applications. It supports vector, full text, regex and metadata search in one system.
What it does
Chroma stores documents and their embeddings, then returns results using semantic, lexical or metadata filters. The page describes object storage underneath, with automatic data tiering to keep costs down. Developers can use it through TypeScript, Python or Rust clients, and run it locally or in the cloud.
Who it's for
Developers building retrieval features, search and agent memory who want a managed search store or one they run themselves. The Apache 2.0 licence makes it easy to try in a local project first.
Pricing and good to know
The core is Apache 2.0 licensed and can run locally. A cloud version is available with a start free option. The page also has a note that the company is joining Replit, so check the current terms before planning a large deployment.
Highlights
- Search by vectors and full text together
- Use BM25 and SPLADE sparse search
- Filter results by metadata
- Fork datasets for tests and rollouts
- Use TypeScript, Python or Rust clients