About turbopuffer
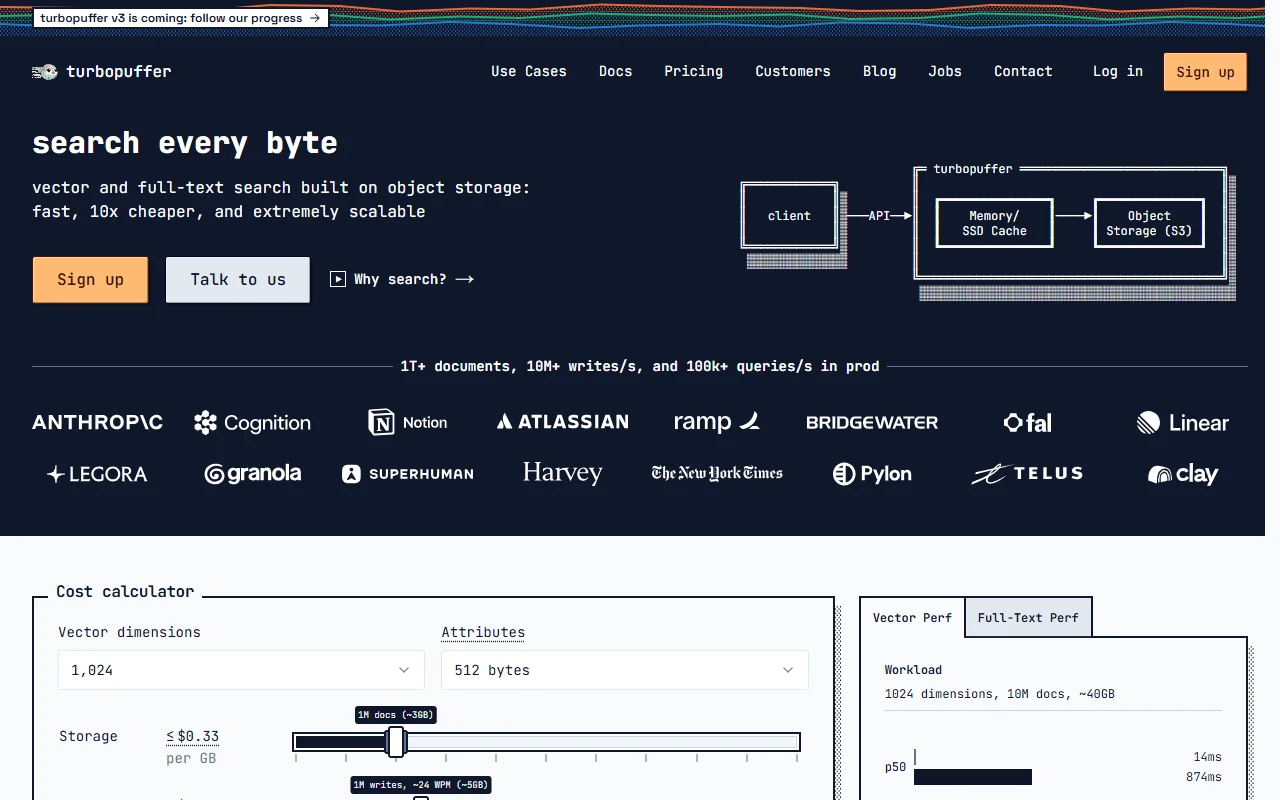
turbopuffer is a search database for vector and full-text queries. It stores its data on object storage and keeps a cache closer to the compute, which is meant to make search fast while keeping costs low.
What it does
turbopuffer indexes vectors and text so applications can run semantic search, keyword search and combined queries. Data lives in object storage such as S3, with a memory and SSD cache in front of it for fast reads. Metadata filters let you narrow results before ranking. The service is accessed through an API, and it is aimed at applications that hold large collections of documents.
Key features
- Store and search vectors in the same database
- Full-text search alongside vector search
- Filter results by metadata
- Data kept on object storage such as S3
- Built for large document collections
Who it's for
The service suits backend teams building search, recommendations or AI retrieval features on large datasets. Small apps with modest data may find a simpler database enough.
Pricing and good to know
The vendor site has a pricing page that lists its plans. Because the service runs on object storage, storage and query costs follow the size of the data. Check the documentation for limits on query size and write rates before you design a system around it.
Highlights
- Store and search vectors in the same database
- Full-text search alongside vector search
- Filter results by metadata
- Data kept on object storage such as S3
- Built for large document collections