About Kokoro
Kokoro is an open-weight text-to-speech model with 82 million parameters, served through a Python package. It is built to be small and fast enough for production use as well as personal projects.
What it does
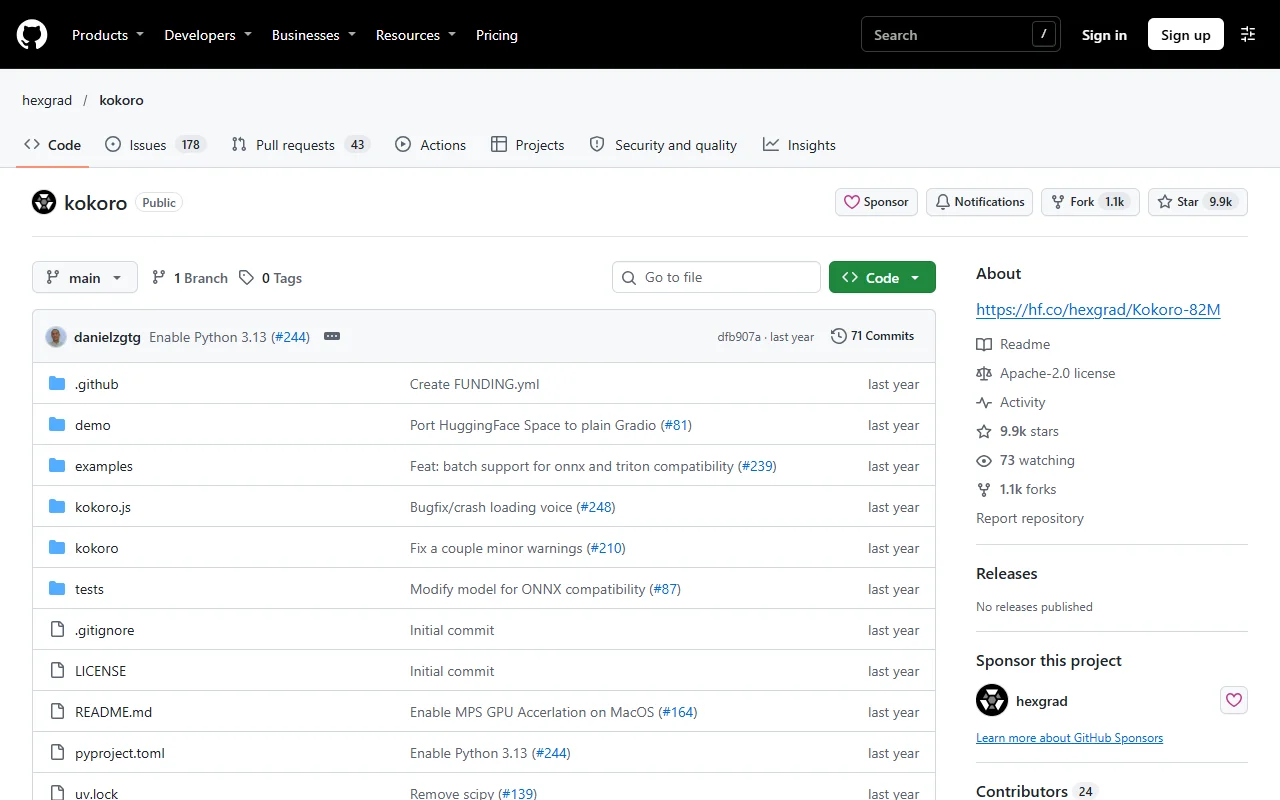
You install the package, load a pipeline, pick a voice and generate audio from text. The project supports batch processing and includes ONNX and Triton compatible builds. The repository also has a JavaScript version and a demo app. The examples show common setup steps, including installing the espeak-ng dependency on some systems.
Key features
- Text to audio from a Python pipeline
- Named voice options
- Batch processing support
- ONNX and Triton builds
- JavaScript package and demo app
Who it's for
Developers adding voice features to apps, hobbyists making audio for personal projects, and teams that need a light model they can host themselves. The examples use named voices, so people who need voice cloning should look at other tools.
Pricing and good to know
The weights and code are released under the Apache-2.0 license, so the model is free to use, including commercially. Speed depends on the hardware you run it on. The model is designed to be light, so it runs well on modest machines.
Highlights
- Turn text into audio in a few lines of Python
- Choose from named voices
- Process many text inputs in a batch
- Use ONNX or Triton builds for deployment
- Run the JavaScript package in a browser